
 BYD Tech
In short
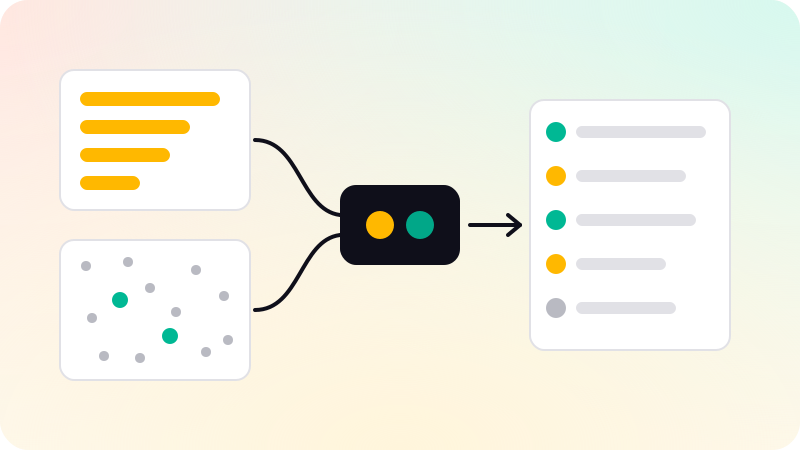
Hybrid search runs a keyword retriever, usually BM25, and a vector retriever on the same query, then merges the two ranked lists into one. Reciprocal rank fusion is the usual default because it uses only rank positions, so it needs no score normalization and almost no tuning; weighted score fusion normalizes both scores and mixes them with a weight you tune on labeled queries. A reranker can then reorder the top of the fused list.
Key points
- BM25 matches exact terms well: identifiers, error codes, names and rare words. Vector search matches meaning: paraphrases and synonyms. Each covers the other’s blind spots.
- BM25 scores a term by its rarity (IDF), with term frequency that saturates and a correction for document length.
- Reciprocal rank fusion scores a document as the sum of
1 / (k + rank)over the lists, with k = 60 from the original paper. - Weighted score fusion needs per-query normalization, because BM25 scores and cosine similarities live on different scales.
- Fusion decides which candidates survive; a cross-encoder reranker decides their final order.
- Tune on a labeled query set broken down by query type, not on a handful of demo queries.
Why one retriever is not enough
A retrieval-augmented system is only as good as the chunks it retrieves (see RAG explained). Two families of retriever dominate. Lexical retrievers such as BM25 score documents by the query’s exact terms. Dense retrievers embed the query and every chunk as vectors and return the nearest neighbors (see what a vector database is).
They fail on different queries. A user who types ERR_CERT_DATE_INVALID wants the chunk containing that exact string, and an embedding model may rank a generic page about certificates above it. A user who asks "how do I get my money back" wants the refund policy, which may never use the words "money back", and BM25 cannot bridge that gap. Hybrid search runs both and merges the results, so a document found by either retriever has a chance to reach the top.
BM25 is not a legacy fallback here. In the BEIR benchmark, which tests retrievers on datasets they were not trained on, the authors call BM25 "a robust baseline".
How BM25 scores a document
BM25 comes from the probabilistic relevance framework that Robertson and Zaragoza survey in "The Probabilistic Relevance Framework: BM25 and Beyond". A document’s score is a sum over the query’s terms, and each term’s contribution has three parts.
score(D, Q) = sum over terms t in Q of
    IDF(t) * tf(t, D) * (k1 + 1) / ( tf(t, D) + k1 * (1 - b + b * |D| / avgdl) )

IDF(t) = log( (N - n(t) + 0.5) / (n(t) + 0.5) )        Robertson/Sparck Jones form
IDF(t) = log( 1 + (N - n(t) + 0.5) / (n(t) + 0.5) )    Lucene form, never negative

tf(t, D)  times term t occurs in document D
|D|       length of D; avgdl = average document length in the collection
N         number of documents; n(t) = number of documents containing t
k1        how fast term frequency saturates (Lucene default 1.2)
b how much length is normalized, 0 to 1 (Lucene default 0.75)- IDF: a term that appears in few documents carries more weight than one that appears everywhere. A match on
pgbouncersays more than a match on "database". - Term frequency saturation: the second occurrence of a term adds less than the first, and the contribution levels off at
k1 + 1. Repeating a keyword fifty times does not make a page fifty times more relevant. - Length normalization: a long document contains more terms by chance, so
bscales term frequency by the document’s length relative to the average.b = 0turns the correction off;b = 1applies it fully.
| Occurrences of the term | Term-frequency factor (k1 = 1.2, b = 0) |
|---|---|
| 1 | 1.00 |
| 2 | 1.38 |
| 5 | 1.77 |
| 20 | 2.08 |
| Limit | 2.20 |
Robertson and Zaragoza note that the model gives no guidance on k1 and b, and that values with b between 0.5 and 0.8 and k1 between 1.2 and 2 work reasonably well in many collections. The (k1 + 1) in the numerator is a common variant; it is the same for every term, so it does not change the ranking. Not every full-text engine implements BM25: PostgreSQL’s ts_rank and ts_rank_cd, for example, rank by term frequency, proximity and weights, and its documentation says they use no global information, so there is no IDF.
Before any of this, an analyzer decides what a "term" is: lowercasing, stemming, stop words, and how punctuation splits tokens. Many default analyzers split on hyphens and other punctuation, so an identifier like INV-2291 may be indexed as two terms. For code, part numbers and error strings, check the analyzer before blaming the ranking.
What vector search catches and what it misses
A dense retriever compresses each chunk into one vector. That is what lets it match meaning across different words, and it is also what loses detail: an exact string, a rare token or a number is one small signal among many in the embedding.
| Query type | Example | BM25 | Vector search |
|---|---|---|---|
| Paraphrase or synonym | "get my money back" for a refund policy | Misses unless the words overlap | Strong |
| Exact identifier | ERR_CERT_DATE_INVALID, INV-2291, a function name | Strong, if the analyzer keeps the token intact | Often ranks similar-looking text above the exact match |
| Rare or new term | A product name coined after the embedding model was trained | Strong: rarity raises IDF | Weak: the model splits it into sub-word pieces with no learned meaning |
| Numbers and versions | "version 3.12" versus "version 3.2" | Matches the token exactly | Treats them as close neighbors |
| Vague or conceptual | "why is the app slow on old phones" | Depends on word overlap | Strong |
| Other languages | A question in Spanish over English documents | Misses | Works with a multilingual embedding model |
Tag your test queries by these types. A single average hides the case that matters: a system can look fine overall and still fail every query that contains an order number.
Learned sparse retrieval: SPLADE in one paragraph
There is a third family between the two. SPLADE (Formal, Piwowarski and Clinchant, SIGIR 2021) uses the masked-language-model head of a BERT-style model to give every query and document a weight for each term in the model’s vocabulary, including expansion terms that do not appear in the text, so a passage about refunds can carry weight for "reimbursement". A log-saturation on the weights and an explicit sparsity regularizer keep most weights at zero, so the result is a sparse vector that an ordinary inverted index can serve, with exact term matching kept. In a hybrid system, a learned sparse model can replace BM25 or sit beside it as a third list to fuse. The cost is a model to run at indexing and query time, and an index that must be rebuilt when that model changes.
Fusion: reciprocal rank versus weighted scores
Each retriever returns a ranked list with its own scores. A BM25 score is unbounded and depends on the query’s length and terms; a cosine similarity sits between -1 and 1, and many embedding models put almost everything between narrow bounds. Adding the raw numbers lets whichever scale is larger decide the result. There are two standard ways around this.
Reciprocal rank fusion (Cormack, Clarke and Buettcher, SIGIR 2009)
  RRF(d) = sum over rankings r of  1 / (k + rank_r(d))      k = 60
  A document absent from a ranking gets nothing from that ranking.

Weighted score fusion (a convex combination)
  norm(s)  = (s - min) / (max - min)        per query, per retriever
  score(d) = alpha * norm(s_vector(d)) + (1 - alpha) * norm(s_bm25(d))
  alpha = 0 is keyword only, alpha = 1 is vector only
Reciprocal rank fusion ignores scores and uses only positions. In the paper, k = 60 was fixed during a pilot study and not changed afterward; the authors found it near-optimal but report that the choice was not critical. The constant flattens the curve, so the top result of one list does not drown out a document ranked well by both. The authors report that RRF beat Condorcet Fuse in every one of their TREC experiments, beat CombMNZ in all but one, and beat the best individual automatic system.
| Property | Reciprocal rank fusion | Weighted score fusion |
|---|---|---|
| Uses | Rank positions only | Normalized scores |
| Tuning | Little: k, and how deep each list goes | The weight alpha, the normalization method and the list depth |
| Keeps score gaps | No: a near-tie and a landslide at rank 1 count the same | Yes, after normalization |
| Sensitive to outliers | No | Yes: min-max on a short list stretches small differences |
| Good default when | You have few labeled queries | You have labeled queries to tune alpha on |
Weighted fusion keeps information that RRF throws away: when one retriever is very confident, the gap survives. It also inherits the weaknesses of normalization. Min-max always maps the lowest score in each list to 0, so the last document in a short list gets nothing from that retriever even when its raw score was close to the top one. Weaviate’s documentation recommends its score-based fusion because it keeps more information; Elasticsearch’s RRF retriever weights every child retriever equally. Both are reasonable, and your labeled queries should decide.
Reciprocal rank fusion in Python
RRF fits in a dozen lines. The input is any number of ranked lists of document ids, best first; nothing about the retrievers leaks into the fusion.
from collections import defaultdict

def rrf(rankings, k=60, top_n=10):
    """Fuse ranked lists of document ids, each best first."""
    scores = defaultdict(float)
    for ranking in rankings:
        for rank, doc_id in enumerate(ranking, start=1):
            scores[doc_id] += 1.0 / (k + rank)
    fused = sorted(scores.items(), key=lambda item: item[1], reverse=True)
    return fused[:top_n]

bm25_ids = ["d3", "d1", "d7", "d4"]
vector_ids = ["d1", "d9", "d3", "d2"]
print(rrf([bm25_ids, vector_ids], top_n=3))
# d1 0.0325  (1/62 + 1/61): second and first
# d3 0.0323  (1/61 + 1/63): first and third
# d9 0.0161  (1/62): only in the vector list
d1 wins without topping BM25, because both retrievers rank it high. Two details matter in practice. First, how deep each list goes: fusing the top 10 of each can only surface what one retriever already put in its top 10, so fuse deeper lists (50 or 100 is common) and cut after fusion. Second, deduplicate by the unit you return: if several chunks of one document are retrieved, decide whether to fuse chunks or documents before you count ranks.
Weighted fusion is just as short. Note what min-max does to d3 below: the top BM25 result is the lowest of three vector scores, so its vector contribution becomes 0.
def min_max(scores):
    lo, hi = min(scores.values()), max(scores.values())
    if hi == lo:
        return {d: 1.0 for d in scores}
    return {d: (s - lo) / (hi - lo) for d, s in scores.items()}

def weighted_fusion(bm25_scores, vector_scores, alpha=0.5, top_n=10):
    """alpha is the vector weight: 0 is keyword only, 1 is vector only."""
    lex, vec = min_max(bm25_scores), min_max(vector_scores)
    ids = set(lex) | set(vec)
    fused = {d: alpha * vec.get(d, 0.0) + (1 - alpha) * lex.get(d, 0.0) for d in ids}
    return sorted(fused.items(), key=lambda item: item[1], reverse=True)[:top_n]

bm25_scores = {"d3": 14.2, "d1": 11.8, "d7": 6.1}
vector_scores = {"d1": 0.83, "d9": 0.79, "d3": 0.71}
print(weighted_fusion(bm25_scores, vector_scores, alpha=0.5, top_n=3))
# d1 0.852, d3 0.5, d9 0.333
How search engines expose it
You rarely need to write fusion yourself if your engine supports it. The names and defaults differ, so read the documentation for the version you run.
| Engine | How hybrid search works | Defaults worth knowing |
|---|---|---|
| Elasticsearch | An rrf retriever with two or more child retrievers, for example a BM25 query and a kNN search | rank_constant (k) defaults to 60; rank_window_size sets how many results each child contributes; children carry equal weight |
| OpenSearch | A hybrid query plus a normalization processor in a search pipeline | Normalization by min_max (the default), l2 or z_score, then a combination such as arithmetic_mean with optional weights |
| Weaviate | A hybrid query with an alpha weight | alpha 0 is keyword only and 1 is vector only, with a server default of 0.75; relativeScoreFusion (min-max scores) is the default since v1.24, rankedFusion uses ranks |
| PostgreSQL | Full-text search and a vector extension queried separately, fused in SQL or in your code | ts_rank is not BM25 and uses no collection statistics |
Where reranking fits
Retrievers score the query and each document separately, which is what makes them fast enough to search millions of chunks. A cross-encoder reranker reads the query and one candidate together and outputs a relevance score. Nogueira and Cho’s "Passage Re-ranking with BERT" is the classic form: the query and passage go in as one input, and a BERT classifier scores the pair, reranking the top 1,000 passages from BM25.
- Retrieve deep lists from each retriever, for example the top 50 to 100 from BM25 and from vector search.
- Fuse them with RRF or weighted fusion. At this stage you care about recall: is the right chunk anywhere in the candidates?
- Rerank the top of the fused list with a cross-encoder. At this stage you care about precision: is the right chunk in the handful you send to the model?
- Keep only the top few for the prompt.
The trade-off is latency and compute: the reranker runs once per candidate, per query. The BEIR authors report that reranking and late-interaction models had the best average zero-shot results, at a high computational cost. Measure whether the gain on your own queries is worth it, and cap the number of candidates you rerank.
How to tune and test a hybrid retriever
- Build a labeled set: real queries, each with the ids of the chunks that answer it. Tag each query by type (identifier, paraphrase, number, conceptual). The method is in how to evaluate a RAG system.
- Measure each retriever alone first: recall at your candidate depth (say recall@50) and a ranking metric such as nDCG@10 or MRR. If one retriever finds almost nothing the other misses, hybrid search may not earn its complexity.
- Start with RRF at k = 60. It has nothing to fit, so it is a fair baseline.
- If you try weighted fusion, sweep alpha on one part of the labeled set and confirm the choice on a held-out part. Look at the per-type breakdown: the best average alpha can still hurt identifier queries.
- Vary list depth before fusion, then add a reranker and measure again, including latency.
- Rerun the set whenever the chunking, the analyzer, the embedding model or the fusion settings change. Changing the embedding model also means re-embedding the whole corpus.
Retrieval quality is upstream of everything else: chunk boundaries decide what a retriever can find (chunking strategies for RAG), and a model that receives the wrong chunks will guess (how to reduce AI hallucinations).
BYD Tech builds AI agents and assistants, retrieval included: the code lives in the client’s GitHub from day one, and AI-assisted work is reviewed by an engineer.
Sources
Checked when this post was written.
- Robertson and Zaragoza: The Probabilistic Relevance Framework: BM25 and Beyond (2009)
- Cormack, Clarke and Büttcher: Reciprocal Rank Fusion outperforms Condorcet and individual Rank Learning Methods (SIGIR 2009)
- Formal, Piwowarski and Clinchant: SPLADE: Sparse Lexical and Expansion Model for First Stage Ranking (2021)
- Thakur et al.: BEIR: A Heterogeneous Benchmark for Zero-shot Evaluation of Information Retrieval Models (2021)
- Nogueira and Cho: Passage Re-ranking with BERT (2019)
- Apache Lucene: BM25Similarity
- Elasticsearch docs: Reciprocal rank fusion
- OpenSearch docs: Normalization processor
- Weaviate docs: Hybrid search
- PostgreSQL docs: Controlling Text Search (ranking search results)


