
 BYD Tech
In short
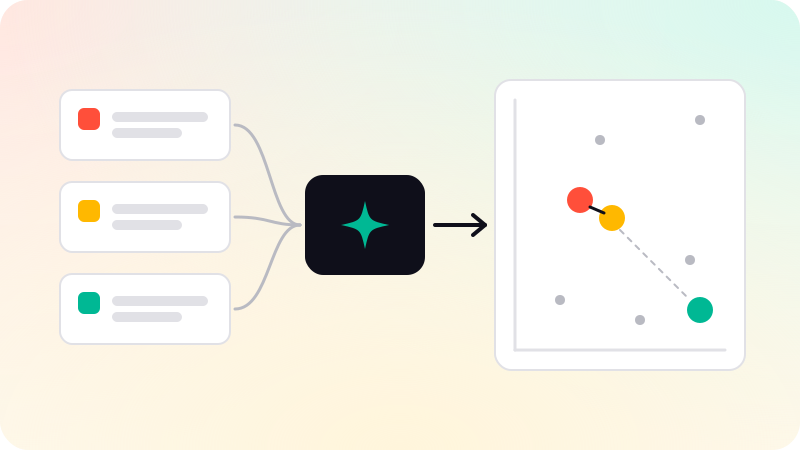
A text embedding is a fixed-length list of numbers that a model produces for a piece of text, placed so that texts with similar meaning end up close together. Models learn this with contrastive training on pairs of related texts, and you compare the vectors with cosine similarity, which for unit-length vectors gives the same ranking as the dot product and Euclidean distance. The practical decisions are the model, the number of dimensions, how the vectors are stored (float, int8 or binary), and whether queries and documents need different prefixes.
Key points
- Cosine similarity, dot product and Euclidean distance rank results identically once vectors are normalized to length 1.
- Contrastive training pulls matching pairs together and pushes the rest of the batch apart, so the training pairs define what "similar" means.
- Matryoshka-trained models let you keep only the leading dimensions of a vector. Normalize again after you cut.
- Int8 storage is four times smaller than float32 and binary is thirty-two times smaller; rescoring the top candidates with full vectors recovers much of what binary loses.
- Many models expect a query prefix or input type that differs from the one for documents. Leaving it out lowers quality without any error.
- Vectors from different models, or different versions of one model, cannot be compared: changing models means re-embedding everything.
What a text embedding is
An embedding model reads a piece of text, a sentence or a passage, and returns a vector: a fixed-length list of floating-point numbers, usually several hundred to a few thousand of them. OpenAI's text-embedding-3-small returns 1,536 numbers by default and text-embedding-3-large returns 3,072. The numbers mean little one by one. What matters is geometry: the model is trained so that texts with similar meaning get vectors pointing in similar directions, and unrelated texts get vectors pointing elsewhere.
That turns "find text that means the same thing" into "find the nearest vectors", which is what semantic search, the retrieval step of RAG, deduplication, clustering and recommendation all do. A search for "how do I get my money back" can find a passage titled "Refund policy" although they share no words. The flip side is that embeddings are fuzzy about exact strings: an error code, a SKU or a version number may not land near its exact match, which is why many systems pair vector search with keyword search, as in hybrid search with BM25 and vectors.
Inside the model, a transformer produces one vector per token, and the embedding model pools them into one, usually by averaging them or by taking the vector of a special token. Everything the input says is compressed into that single point, which is why a long passage covering three topics embeds less sharply than three short ones.
How embedding models are trained
A pretrained language model such as BERT does not give good sentence vectors out of the box. Reimers and Gurevych addressed this in Sentence-BERT (EMNLP 2019): they fine-tuned BERT in siamese and triplet setups, copies of one network with shared weights each encoding one sentence, so that the output vectors can be compared with cosine similarity. The payoff was speed. Scoring sentence pairs with BERT itself means running the model on every pair; with separate sentence vectors, each sentence is encoded once. The authors report that finding the most similar pair among 10,000 sentences drops from about 65 hours with BERT to about 5 seconds with SBERT.
Current embedding models are trained contrastively. Each training example is a pair of texts that belong together: a question and the passage that answers it, a title and its body, a post and a reply. The model encodes a batch of pairs, and a loss called InfoNCE rewards it when each query's vector is closer to its own passage than to every other passage in the batch. Those other passages are free "in-batch negatives", so a larger batch gives the model more to tell apart. In E5, Wang and colleagues pre-trained on a large curated set of weakly supervised text pairs they call CCPairs, with a batch size of 32,768 to increase the number of negatives, and then fine-tuned on labeled data. They report E5 as the first model to beat the BM25 baseline on the BEIR retrieval benchmark without using labeled data.
- Hard negatives are passages that look relevant but are not. Training on them teaches finer distinctions than random in-batch negatives.
- The loss divides similarities by a small temperature (E5 uses 0.01), which sharpens the gap between the right pair and the rest.
- The training pairs define what "similar" means. A model trained on question-answer pairs ranks answers to a question; a model trained on paraphrases ranks rewordings. These are different tasks, and a model can be good at one and average at the other.
Because the query and each passage are encoded separately, this design is called a bi-encoder, and passage vectors can be computed ahead of time. A cross-encoder that reads the query and a passage together is more accurate and far slower, so it is used to rerank a short candidate list, as described in RAG explained.
Cosine similarity, dot product and Euclidean distance
Three measures are in common use. Cosine similarity is the dot product divided by both vector lengths, so it compares direction only. The dot product multiplies matching components and sums them, so a longer vector scores higher. Euclidean (L2) distance is the straight-line distance between the two points.
| Measure | Formula | Range | Affected by vector length? |
|---|---|---|---|
| Cosine similarity | Dot product divided by the product of the two lengths | -1 to 1, higher is closer | No |
| Dot product | Sum of the products of matching components | Unbounded, higher is closer | Yes |
| Euclidean distance | Square root of the sum of squared differences | 0 and up, lower is closer | Yes |
Once every vector is normalized to length 1, the three agree. Cosine becomes the dot product, and the squared Euclidean distance becomes 2 − 2 × cosine, which falls as cosine rises, so all three return the same ranking. OpenAI's documentation says its embeddings are already normalized to length 1, that cosine similarity can then be computed slightly faster with a dot product, and that cosine similarity and Euclidean distance give identical rankings. Normalize once when you write a vector and use the dot product at query time.
import math

def normalize(v):
    n = math.sqrt(sum(x * x for x in v))
    return [x / n for x in v] if n else v

def dot(a, b):
    return sum(x * y for x, y in zip(a, b))

def cosine(a, b):
    return dot(a, b) / math.sqrt(dot(a, a) * dot(b, b))

def euclidean(a, b):
    return math.sqrt(sum((x - y) ** 2 for x, y in zip(a, b)))

a, b = [0.9, 0.1, 0.4], [0.7, 0.3, 0.5]
ua, ub = normalize(a), normalize(b)

print(round(cosine(a, b), 6), round(dot(ua, ub), 6))  # 0.953556 twice
print(round(euclidean(ua, ub) ** 2, 6),
      round(2 - 2 * dot(ua, ub), 6))                 # 0.092887 twice

def shorten(v, dims):
    # Matryoshka-trained models only: keep the leading dims, renormalize.
    return normalize(v[:dims])
Without normalization the measures disagree. Some models are trained with a dot-product objective and expect it at query time; their model card says so. Use the measure the model was trained with, and set the index's distance metric to match it.
A raw cosine score is not a probability, and its useful range shifts from model to model: one model may score unrelated texts near 0.1 and another near 0.7. Choose any relevance cutoff on labeled examples from your own data, not from a number that worked for someone else's model.
Dimensions and Matryoshka embeddings
More dimensions can hold finer distinctions, and they cost memory and search time in direct proportion. A float32 vector of 1,536 dimensions takes 6,144 bytes; ten million of them take about 61 GB before any index overhead, and an approximate index such as HNSW stores its graph links on top.
Matryoshka Representation Learning (Kusupati and colleagues, 2022) makes the length adjustable after training. The training loss is applied to the full vector and also to its leading slices, for example the first 64, 128 and 256 dimensions, so the first dimensions carry the coarse meaning and later ones add detail, like nested dolls. The authors report up to 14 times smaller embeddings for ImageNet-1K classification at the same accuracy, and up to 14 times real-world speed-ups for large-scale retrieval.
Several APIs expose this. OpenAI's text-embedding-3 models accept a dimensions parameter, and the documentation says it shortens the embedding without it losing its concept-representing properties; if you cut a vector yourself, it says to normalize it again, as shorten() above does. Cohere's documentation lists a set of supported output dimensions for its newer Embed models. Only cut vectors from a model trained this way: the leading dimensions of an ordinary model are not a summary of the rest.
- Short vectors suit a two-stage search: run the fast first pass on the leading dimensions, then rescore the candidates with the full vectors.
- Choose the length on your own evaluation set. Measure recall at each candidate length and stop where the gain no longer justifies the memory.
Token limits and truncation
Every embedding model has a maximum input length, counted in its own tokens. OpenAI lists 8,192 tokens for its text-embedding-3 models. The model card for the open E5 base model says long texts are truncated to at most 512 tokens. What happens past the limit depends on the API and library: some reject the input, others cut it and embed only the start.
- Silent truncation is the dangerous case. A passage whose answer sits past the cutoff is still indexed, but its vector says nothing about the answer, and nothing in the logs explains why it is never found.
- Count tokens with the model's own tokenizer before embedding, and split or log anything over the limit.
- A high limit is not a reason to embed long passages. One vector for a long passage blends its topics, and smaller chunks retrieve more precisely; see chunking strategies for RAG.
- A model's maximum is what it accepts, not necessarily where it works best. Test at the passage lengths you plan to store.
Quantization: float32, int8 and binary
Quantization stores each dimension in fewer bits. The vector keeps its number of dimensions; each number gets coarser.
| Format | Bits per dimension | Size versus float32 | How it works | Typical use |
|---|---|---|---|---|
| float32 | 32 | Same | Full precision | Small collections; rescoring candidates |
| int8 (scalar) | 8 | 4 times smaller | Each dimension mapped onto 256 levels, using ranges taken from sample vectors | Large collections that still need high recall |
| Binary | 1 | 32 times smaller | 1 where the value is positive, 0 otherwise; compared with Hamming distance | A fast first pass over very large collections, followed by rescoring |
Scalar (int8) quantization finds each dimension's range on a calibration sample of embeddings and maps it onto 256 levels. Qdrant's documentation says this cuts the memory per vector by a factor of 4, and reports that in its experiments the error it introduces is usually less than 1%. The Sentence Transformers documentation notes that the calibration set has a large influence on the result, so calibrate on vectors from your own corpus.
def calibrate(sample):
    # Per-dimension min and max from a sample of your own embeddings.
    lo = [min(col) for col in zip(*sample)]
    hi = [max(col) for col in zip(*sample)]
    return lo, hi

def to_int8(v, lo, hi):
    out = []
    for x, l, h in zip(v, lo, hi):
        x = min(max(x, l), h)                    # clip to the calibrated range
        step = (h - l) / 255 or 1.0
        out.append(round((x - l) / step) - 128)  # -128 to 127
    return out

lo, hi = calibrate([[0.1, -0.5], [0.3, 0.2], [-0.2, 0.4]])
print(to_int8([0.25, 0.0], lo, hi))  # [102, 14]
Binary quantization keeps only the sign of each dimension: one bit instead of 32. Similarity becomes Hamming distance, the number of differing bits, which a CPU computes with an XOR and a bit count. The loss is larger, so binary search is used as a first pass: fetch more candidates than you need (oversampling), then rescore them with full-precision vectors. The Sentence Transformers documentation reports that with rescoring, binary quantization preserves up to about 96% of retrieval performance. Qdrant reports recall around 0.98 for several OpenAI and Cohere models with 2 to 4 times oversampling and rescoring, and says binary quantization is efficient only for high-dimensional vectors; in its own sweep, a 512-dimension vector kept much less accuracy than a 3,072-dimension one.
def to_bits(v):
    # One bit per dimension: 1 where the value is positive.
    return sum(1 << i for i, x in enumerate(v) if x > 0)

def hamming(a, b):
    return bin(a ^ b).count("1")  # number of differing bits

def dot(a, b):
    return sum(x * y for x, y in zip(a, b))

def search(query, docs, k=5, oversample=4):
    # docs: list of (doc_id, bits, full_vector); full vectors can sit on disk
    q_bits = to_bits(query)
    # Pass 1: Hamming scan over the bits, keep k * oversample candidates
    pool = sorted(docs, key=lambda d: hamming(q_bits, d[1]))[:k * oversample]
    # Pass 2: rescore the pool with full-precision vectors
    pool.sort(key=lambda d: dot(query, d[2]), reverse=True)
    return [doc_id for doc_id, _, _ in pool[:k]]

vecs = {"a": [0.2, -0.1, 0.4], "b": [-0.3, 0.5, -0.2], "c": [0.1, 0.2, 0.3]}
docs = [(i, to_bits(v), v) for i, v in vecs.items()]
print(search([0.3, -0.2, 0.5], docs, k=2, oversample=1))  # ['a', 'c']
Quantization and Matryoshka shortening stack: a shortened vector can also be quantized. Each step costs some recall, so measure the combination you plan to ship against an exact full-precision search on real queries.
Symmetric and asymmetric search: prefixes and input types
In symmetric search both sides are the same kind of text: duplicate questions, or sentences that paraphrase each other. In asymmetric search they differ: a short question on one side, a long passage that answers it on the other. A question and its answer do not look alike, so many models encode the two sides differently.
Often this is done with a marker on the input. E5 adds "query: " and "passage: " prefixes; its authors write that they break the symmetry between the two sides this way and that the asymmetric design turns out to be important for some retrieval tasks. The E5 model card says the prefixes are required, that leaving them out degrades performance, and that symmetric tasks such as semantic similarity should use "query: " on both sides. Cohere's API takes an input_type parameter instead: search_document for the passages you index, search_query for queries, and classification or clustering for those tasks.
| Task | Query side | Document side |
|---|---|---|
| Question-to-passage retrieval (asymmetric) | The query prefix or input type | The document prefix or input type |
| Duplicate or paraphrase detection (symmetric) | One shared setting, as the model card says | The same setting |
| Clustering or classification | Not used | The clustering or classification setting, where the model has one |
Getting this wrong raises no error; results just get worse. Read the model card, apply prefixes in one function that every embedding call goes through, and cover them in tests.
Choosing an embedding model
The Massive Text Embedding Benchmark (MTEB, Muennighoff and colleagues) is the usual starting point. The original paper covers 8 embedding tasks, 58 datasets and 112 languages, and its public leaderboard ranks models per task. The paper's main finding is a good rule: no particular text embedding method dominates across all tasks. Read the retrieval scores on data closest to yours, not the overall average.
- Domain: legal, medical, code and support tickets use vocabulary that general web text does not. A model that leads the leaderboard may not lead on your documents.
- Language: check every language you serve, and mixed-language queries. Multilingual models can place a question in one language near an answer in another.
- Input length: the token limit has to fit your chunk size with room to spare.
- Dimensions and storage: whether the model supports Matryoshka shortening, and how well its vectors hold up under int8 or binary storage.
- License and hosting: open-weight models can run on your own servers, which matters for data residency, but check that the license allows your use. Hosted models remove the serving work and add a dependency on the provider's versions and retirements; see AI model deprecation.
- Latency: documents are embedded once at indexing time, but every query waits for its embedding.
Then test on your own data. Take a few hundred real queries, label the passages that answer them, and compare recall@k for two or three candidate models with your own chunking. How to evaluate RAG shows how to build that set.
Changing models means re-embedding
Vectors from two models live in different spaces. Even with the same number of dimensions, the axes mean different things, so a query embedded with a new model cannot be compared with documents embedded with the old one. The same holds for a new version of the same model.
- Store the model name, version, dimensions, prefix scheme and quantization with every index.
- Build a second index with the new model beside the old one, from the stored source text.
- Run your evaluation set against both and compare recall.
- Switch queries to the new index in one step, so no search ever mixes the two models, and keep the old index until the new one has handled real traffic.
- Delete the old index.
Keep the source text and chunk boundaries, not only the vectors; without them, a model change means parsing every document again. For where the vectors are stored and searched, see what is a vector database.
If you want semantic search or a RAG feature built into your product, see our AI agent development service: the code lives in your GitHub from day one, and AI-assisted work is reviewed by an engineer.
Sources
Checked when this post was written.
- Reimers and Gurevych, Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks (arXiv, EMNLP 2019)
- Wang et al., Text Embeddings by Weakly-Supervised Contrastive Pre-training (E5, arXiv)
- Kusupati et al., Matryoshka Representation Learning (arXiv)
- Muennighoff et al., MTEB: Massive Text Embedding Benchmark (arXiv)
- OpenAI API documentation: Vector embeddings
- Cohere documentation: Embeddings
- E5 base v2 model card (Hugging Face)
- Qdrant documentation: Quantization
- Sentence Transformers documentation: Embedding Quantization


