 BYD Tech
The short answer
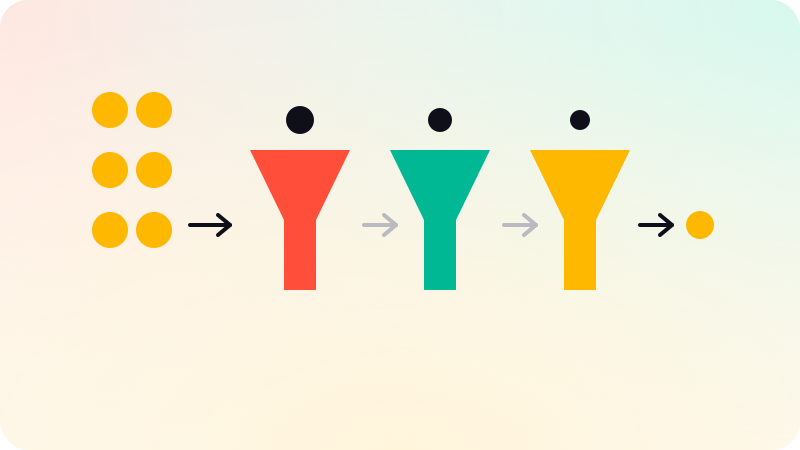
To reduce LLM costs, first measure cost per feature and per request, then use the smallest model that does each task well, cache the parts of the prompt that repeat, send work that can wait through a batch API, and trim what goes into the context. Anthropic’s documentation, for example, prices cache reads at a fraction of normal input tokens and batch requests at half price. Set spending caps and per-user limits so growth or abuse cannot surprise you.
Key points
- Measure cost per feature before optimizing anything.
- Use the smallest model that passes your tests for each task.
- Prompt caching makes repeated instructions and documents much cheaper.
- Batch APIs halve the price of work that can wait.
- Spending caps and per-user limits protect you from surprises.
Measure first
Model providers charge per token: input tokens you send and output tokens the model writes. Log the tokens of every request with the feature and user it belongs to. Usually a few features, or a few heavy users, account for most of the bill, and those are where to start.
The main levers
| Lever | How it saves | Good for |
|---|---|---|
| Right-size the model | Smaller models cost far less per token | Classification, extraction, routing, simple replies |
| Prompt caching | Repeated prompt prefixes are billed at a reduced rate | Long instructions, documents or tool lists reused across requests |
| Batch processing | Lower price for asynchronous jobs | Overnight reports, bulk tagging, evaluations |
| Trim the context | Fewer input tokens per request | Chat history, retrieved documents, verbose tool output |
| Limit output length | Fewer output tokens, usually the pricier kind | Summaries and structured answers |
| Reuse results | Skip the model call entirely | Identical questions, stable answers |
Anthropic’s documentation gives concrete figures: cache reads cost a small fraction of the base input price, and the Message Batches API reduces costs by 50 percent for requests that do not need an immediate answer. OpenAI and Google offer similar caching and batch options.
Route by task
- Split the feature into steps: understanding the request, retrieving, answering, checking.
- Try the smallest model on each step against your test set.
- Keep the larger model only for the steps where the small one fails.
- Rerun the tests whenever you change a model, so savings do not cost quality.
Without a test set you cannot tell whether a cheaper model is good enough. See How to evaluate AI agents.
Guardrails on spending
- A monthly spending cap on the provider account, with alerts below it.
- Per-user and per-minute rate limits on your own API.
- A maximum number of steps per agent run, so a loop cannot run forever.
- Cost per active user on your dashboard, next to revenue per user.
Multi-agent designs multiply token use, so check they earn it. See Multi-agent systems. Model choice and spending limits are part of the design in AI agent development.
Sources
Checked when this guide was written.